

Prompt Injection: The Silent Failure Mode of Enterprise AI Security
Prompt Injection: The Silent Failure Mode of Enterprise AI Security
As organizations rapidly adopt enterprise AI security frameworks and deploy multi-agent AI systems for document processing, email triage, and decision automation, a new and often overlooked risk has emerged: prompt injection.
This is not just another addition to the evolving AI threat landscape. It is one of the most critical AI security risks impacting modern LLM-integrated applications, especially in environments where automation and autonomy are increasing.
What Is Prompt Injection in AI?
Prompt injection is a type of AI attack vector that targets how large language models (LLMs) interpret instructions. These models rely on structured inputs, including system prompts, user inputs, and external data sources.
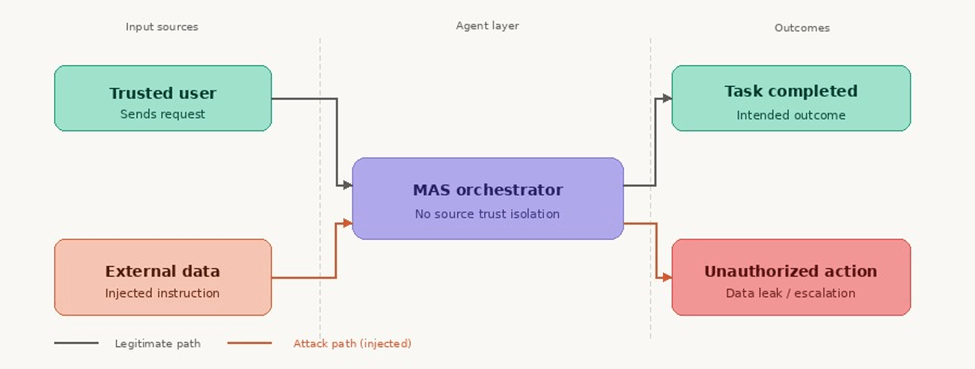
A prompt injection attack occurs when malicious instructions are embedded within content that the model is supposed to process, not execute.
These attacks can take different forms:
- Direct injections through user inputs
- Indirect injections hidden in documents, emails, or web pages
Unlike traditional AI model vulnerabilities, this threat does not exploit software flaws. Instead, it manipulates the model’s reasoning layer, making it a unique challenge in generative AI security.
Why Prompt Injection Is a Critical Enterprise AI Risk
In multi-agent AI systems, the risk of LLM vulnerabilities increases significantly. Agents are designed to:
- Delegate tasks to sub-agents
- Access enterprise data stores
- Trigger downstream APIs
A single malicious instruction can propagate across the system, creating a chain reaction. This makes prompt injection in multi-agent systems particularly dangerous.
What makes this worse for mid-size organizations is the imbalance:
- Attackers need only one successful injection
- Defenders must secure every input, output, and integration point
Traditional cybersecurity measures fail here because this is not a network-level issue. The attack exists inside the model’s decision-making process, beyond the reach of standard perimeter defenses.
OWASP and the Growing AI Threat Landscape
The OWASP has identified prompt injection as a top risk in its guidance on LLM security.
According to OWASP, these attacks can:
- Bypass access controls
- Manipulate outputs
- Trigger unauthorized actions
This positions prompt injection as a core concern in enterprise AI risk management and AI governance frameworks.
Why Enterprises Are Especially Vulnerable
Mid-size enterprises face unique challenges in managing AI data security and AI automation security risks:
- Lean security teams
- Rapid adoption of AI tools
- Limited visibility into AI decision flows
As organizations scale secure AI deployment, the level of autonomy given to AI agents increases. With that, the impact of a successful prompt injection attack becomes more severe.
The more powerful the system, the greater the risk.
Defensive Strategies for Securing Enterprise AI Applications
To reduce exposure and strengthen AI compliance security, organizations should adopt a layered defense approach:
- Input and Output Sanitization
Ensure all incoming and outgoing data is validated to prevent malicious instructions from being executed.
- Context-Aware Trust Scoring
Assign trust levels to external data sources to reduce risks from unverified inputs.
- Real-Time Monitoring and Audit Logging
Track agent behavior using AI audit logging to detect anomalies and policy violations early.
- Least-Privilege Access Control
Design systems with least privilege AI systems principles, limiting what each agent can access or execute.
The Path Forward: Rethinking AI Security
Addressing prompt injection is not a one-time fix. It requires a shift in how organizations approach enterprise AI security.
AI agents must be treated as active participants in the security model, not just tools. This means:
- Defining clear trust boundaries
- Strengthening AI access control models
- Embedding security into AI workflows
As AI governance in enterprises continues to evolve, organizations that prioritize security at the architecture level will be better positioned to manage emerging risks.
Conclusion
Prompt injection is no longer a theoretical concern. It is a real and growing threat within the modern AI threat landscape.
As enterprises continue investing in automation and generative AI security, the need for proactive, structured defenses becomes critical.
Securing AI is not just about protecting systems, it’s about ensuring trust in every decision those systems make.
Categories
- Accessibility solutions (3)
- AI / LLMOps (AI Observability & Monitoring) (3)
- AI & Automation (17)
- AI Governance & Responsible AI (4)
- AI Security (4)
- Android (17)
- Angular JS (1)
- API & Integration / Developer Tools (1)
- Apple (3)
- Artificial Intelligence (1)
- Artificial Intelligence (AI) (16)
- AV & Collaboration Technology (2)
- AWS Cloud Computing (2)
- AWS DMS (6)
- AWS RDS (12)
- Azure (3)
- BI & ANALYTICS (16)
- Cloud Computing & AI (5)
- Cloud Identity & Directory Services (1)
- Cloud Migration (12)
- Cloud Security & Identity Management (3)
- Company News (5)
- Continuous integration and continuous deployment (2)
- Cybersecurity (7)
- Data Analytics (12)
- Data Engineering (8)
- Data Governance & Compliance (6)
- Data Management (5)
- Data Migration (9)
- Data Quality (1)
- Data Quality & Data Governance (1)
- DBA (10)
- DevOps (1)
- Email Security (1)
- Endpoint Management / Device Management (1)
- Enterprise AI / AI Governance (1)
- Enterprise AI / AI Implementation Best Practices (1)
- Enterprise AI & Intelligent Automation (2)
- Enterprise Mobility & Security (1)
- Enterprise Software Integration / Backend Development (1)
- Enterprise Technology (1)
- Enterprise UX/UI Design (1)
- Goldengate (19)
- Google (2)
- Hadoop (3)
- HPNA (1)
- Ios (10)
- ios 10 (2)
- iPad (3)
- iPhone (3)
- Licensing (7)
- Linux (13)
- Machine Learning Solutions (1)
- Marketing Technology (1)
- Microsoft 365 (1)
- Microsoft 365 Development / APIs (1)
- Microsoft 365 Security & Compliance (4)
- Microsoft Configuration Manager (SCCM / MECM) (1)
- Microsoft Dynamics 365 (4)
- Microsoft Marketplace (1)
- Microsoft Office (5)
- Microsoft Purview (3)
- Microsoft SharePoint & Security (1)
- Microsoft Teams / Collaboration Tools (1)
- Microsoft Teams Security & Compliance (2)
- Mobile (2)
- Network Automation (5)
- Network Security Services (1)
- News (21)
- Operating System (1)
- Oracle (37)
- oracle consulting (3)
- PostgreSQL (1)
- Quantum Computing (1)
- Quickbooks (1)
- SEO (1)
- Software Development (33)
- Systems Automation (2)
- Tech (3)
- Technology (51)
- UI (13)
- Uncategorized (8)
- UX (9)
- VSTO (1)
- Web Development (1)
- Windows (9)
- wordpress (1)