

Data Poisoning in Multi-Agent AI: Enterprise Security Risks
Data Poisoning in Enterprise Multi-Agent Systems: The Inverted Economics of a Quiet Threat
In enterprise multi-agent systems, data is the foundation of every decision. When that data is compromised, the entire system becomes vulnerable to manipulation—quietly, and at scale. This is where data poisoning attacks emerge as one of the most critical yet underestimated AI security risks facing organizations today.
At its core, AI data poisoning occurs when malicious or corrupted data is introduced into an AI system to influence its behavior. Unlike prompt injection, which operates at runtime, poisoning works silently in the background—inside datasets, knowledge bases, and feedback loops.
In modern agentic AI environments, the scope of machine learning security has expanded. Poisoned data can enter through pre-training datasets, fine-tuning pipelines, RAG (Retrieval-Augmented Generation) knowledge bases, persistent agent memory, third-party tool integrations, or even inter-agent communication. The model itself is not directly compromised; instead, its inputs are subtly manipulated, leading to outcomes that appear reasonable in isolation but are misaligned at a system level. This makes LLM security a growing concern in enterprise deployments.
A landmark study in October 2025 by Anthropic, the UK AI Security Institute, and the Alan Turing Institute demonstrated how small the attack surface really is. Researchers found that roughly 250 malicious documents could successfully create backdoors in a large language model, regardless of its size. For a 13B-parameter model, this represents just 0.00016% of training data.
This finding reshapes the economics of AI attack vectors in enterprise systems. Creating a few hundred adversarial documents is trivial, but maintaining the integrity of enterprise AI pipelines—training corpora, retrieval indexes, and tool registries—is significantly more complex and resource-intensive.
Why Multi-Agent Systems Amplify the Risk
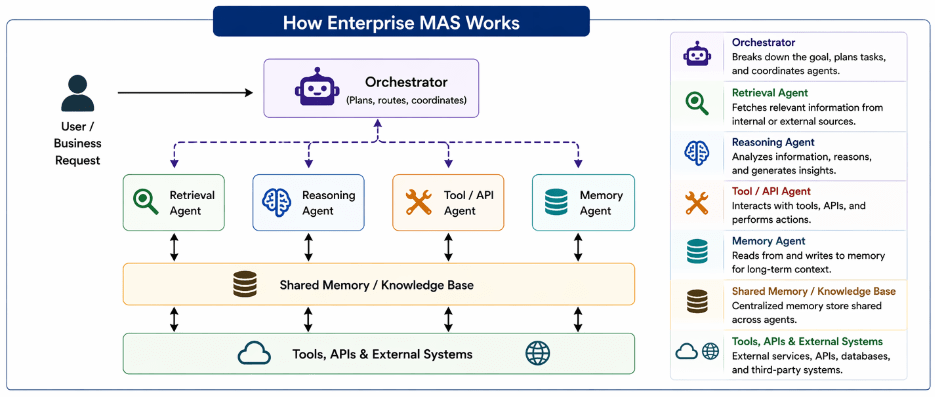
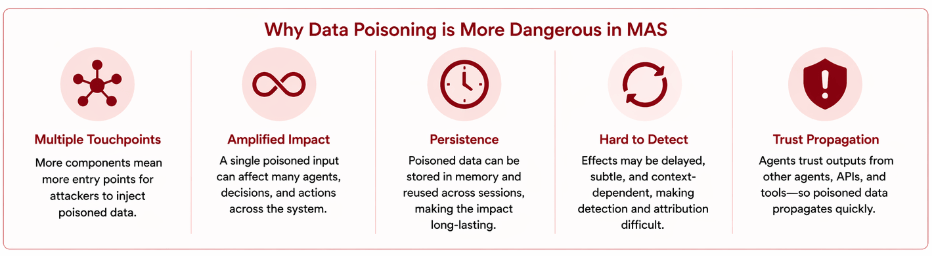
Multi-agent systems (MAS) amplify this risk in three structural ways.
First, agents tend to trust each other implicitly. Research in 2025 showed that 82% of tested models executed malicious instructions when those instructions were relayed by another agent—even when the same models rejected identical inputs from users. This exposes a critical AI agent trust vulnerability.
Second, failures cascade. A retrieval agent may ingest poisoned content, a planning agent treats it as valid context, an execution agent triggers an action, and a validation agent approves the already corrupted output. These cascading failures highlight how AI system vulnerabilities can spread across interconnected agents.
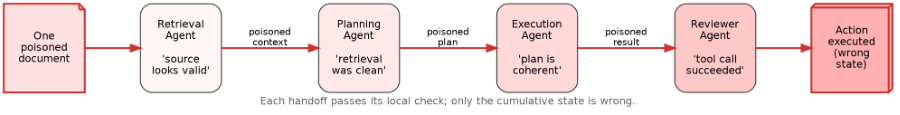
Third, persistent memory transforms temporary attacks into long-term risks. The 2025 MINJA attack demonstrated over 95% success in exploiting memory-based agents through regular interactions alone. This underscores the growing risk of persistent memory attacks in AI agents and the importance of securing feedback loops.
The Subtle Nature of AI Model Poisoning
One of the biggest challenges with data poisoning in machine learning is that it rarely causes immediate or obvious failures. Instead, it introduces:
- Subtle biases
- Targeted misbehavior
- Delayed errors
These issues often go unnoticed until they manifest in critical outcomes, such as incorrect approvals, flawed recommendations, or compliance violations.
Real-world incidents that ground the taxonomy
The theoretical risks have already manifested in production systems. A selected incident timeline:
| Date | Incident | Class | What it demonstrated |
| Aug 2024 | Slack AI data exfiltration | P4 + P2 | RAG poisoning combined with social engineering enabled cross-channel data leakage |
| Oct 2024 | Prompt Infection | P6 | Self-replicating instructions propagating across a multi-agent system |
| Oct 2024 | ChatGPT ZombAI | P5 | First promptware-native command-and-control via poisoned memory |
| Early 2025 | Hugging Face supply-chain | P1 | ~100 poisoned models uploaded to a public registry |
| Early 2025 | Nature Medicine medical poisoning | P1 | 0.001% token poisoning evaded all standard benchmarks |
| Oct 2025 | 250-document backdoor study | P1 | Near-constant poison count across model scales |
| Oct 2025 | Unit 42 agent session smuggling | P6 | Sub-agent coercing an orchestrator into unauthorized financial actions |
The Observability Gap in Enterprise AI
Despite rapid adoption, visibility into AI behavior remains limited. While nearly 90% of organizations are deploying or planning to deploy AI systems, only about 17% report having continuous monitoring in place. This creates a significant AI observability gap, where AI security risks can grow undetected.
In such environments, RAG security risks and AI feedback loop poisoning risks compound over time. Each agent interaction appears valid in isolation, masking the larger issue. Organizations often only discover the problem after a financial transaction, data modification, or regulatory audit reveals inconsistencies.
A Shift in Enterprise AI Security Strategy
The “250-document” finding is more than a technical insight—it’s a wake-up call for enterprise AI security challenges. It highlights how minimal effort from an attacker can have disproportionate impact, especially in complex, interconnected systems.
To address this, organizations must rethink their approach to AI risk management frameworks and secure AI pipelines. This includes:
- Strengthening data validation across all ingestion points
- Monitoring agent interactions for anomalies
- Securing knowledge bases and retrieval systems
- Implementing robust AI governance and compliance controls
- Improving visibility into agent decision-making processes
As autonomous agents become more prevalent, ensuring AI trust and safety is no longer optional—it’s foundational.
Categories
- Accessibility solutions (3)
- AI / LLMOps (AI Observability & Monitoring) (3)
- AI & Automation (17)
- AI Governance & Responsible AI (4)
- AI Security (4)
- Android (17)
- Angular JS (1)
- API & Integration / Developer Tools (1)
- Apple (3)
- Artificial Intelligence (1)
- Artificial Intelligence (AI) (16)
- AV & Collaboration Technology (2)
- AWS Cloud Computing (2)
- AWS DMS (6)
- AWS RDS (12)
- Azure (3)
- BI & ANALYTICS (16)
- Cloud Computing & AI (5)
- Cloud Identity & Directory Services (1)
- Cloud Migration (12)
- Cloud Security & Identity Management (3)
- Company News (5)
- Continuous integration and continuous deployment (2)
- Cybersecurity (7)
- Data Analytics (12)
- Data Engineering (8)
- Data Governance & Compliance (6)
- Data Management (5)
- Data Migration (9)
- Data Quality (1)
- Data Quality & Data Governance (1)
- DBA (10)
- DevOps (1)
- Email Security (1)
- Endpoint Management / Device Management (1)
- Enterprise AI / AI Governance (1)
- Enterprise AI / AI Implementation Best Practices (1)
- Enterprise AI & Intelligent Automation (2)
- Enterprise Mobility & Security (1)
- Enterprise Software Integration / Backend Development (1)
- Enterprise Technology (1)
- Enterprise UX/UI Design (1)
- Goldengate (19)
- Google (2)
- Hadoop (3)
- HPNA (1)
- Ios (10)
- ios 10 (2)
- iPad (3)
- iPhone (3)
- Licensing (7)
- Linux (13)
- Machine Learning Solutions (1)
- Marketing Technology (1)
- Microsoft 365 (1)
- Microsoft 365 Development / APIs (1)
- Microsoft 365 Security & Compliance (4)
- Microsoft Configuration Manager (SCCM / MECM) (1)
- Microsoft Dynamics 365 (4)
- Microsoft Marketplace (1)
- Microsoft Office (5)
- Microsoft Purview (3)
- Microsoft SharePoint & Security (1)
- Microsoft Teams / Collaboration Tools (1)
- Microsoft Teams Security & Compliance (2)
- Mobile (2)
- Network Automation (5)
- Network Security Services (1)
- News (21)
- Operating System (1)
- Oracle (37)
- oracle consulting (3)
- PostgreSQL (1)
- Quantum Computing (1)
- Quickbooks (1)
- SEO (1)
- Software Development (33)
- Systems Automation (2)
- Tech (3)
- Technology (51)
- UI (13)
- Uncategorized (8)
- UX (9)
- VSTO (1)
- Web Development (1)
- Windows (9)
- wordpress (1)